Key Takeaways
- Keyword and tag-based search hits a structural ceiling in creative hiring. Lexical search misses the visual signal that makes a portfolio worth shortlisting.
- Multimodal retrieval is an architectural fix, not a tuning exercise. Embedding models place portfolio images, resume text, and search queries in one vector space, enabling text-to-image, image-to-image, and semantic ranking. On an expert-curated benchmark, embedding-based search puts the right portfolio piece in the top 5 results 74% of the time and in the top 20 every time.
- Embedding-based search is the right long-term investment for creative staffing. Higher upfront cost buys better-matched shortlists, faster placements, and a clear path to other modalities, provided relevance is evaluated rigorously and continuously.
Listen: Beyond keywords: multimodal embedding for creative hiring.
The search for creative talent is an information retrieval (IR) problem with a mismatch at its core: the query is usually visual or conceptual, but the index is text.
When a client needs a Graphic Designer, a Game Artist, or a Motion Designer, what they are really asking for is a particular visual sensibility: a style, a level of craft, a way of handling light, form, or typography. That information lives in the portfolio itself. Yet the systems we use to find that talent have traditionally relied on text: job titles, skill keywords, and portfolio tags that narrow the search. This default method used for most of the history of talent platforms is lexical search.
Lexical search puts a lot of weight on two groups of people. Creators / Talent carry the burden of tagging their work thoroughly and in exactly the vocabulary a future Recruiter might use, across every role their work could plausibly fit. Recruiters carry the burden of translating a client's often loosely described brief like “something moody and cinematic, but still playful” into keywords that might match those tags, while holding a deep mental model of creative styles. When either side of that translation breaks, good candidates stay invisible, shortlists take longer to build, and time to placement grows.
So the question becomes: What if the visual content, along with what the talent shares in their resume and portfolio, could drive retrieval directly?
The answer is not a better tagging taxonomy or a smarter synonym list. It is an architectural change—retrieval based on multimodal embedding models.
Why keyword and tag search are architecturally the wrong tools
Where creative sourcing breaks today
A creative brief carries multiple things at once: an artifact (a packaging die-line, a UX flow, a character sculpt), an object (what the work depicts), a style/sensibility (muted, filmic, hand-lettered), and a medium (canvas, sculpt). Keyword search flattens everything into tags. The surrounding infrastructure makes this harder. Applicant tracking systems (ATS) and career sites were built to index resumes, not visual assets or portfolios spread across personal sites, site builders, and platforms. In practice, Recruiters open portfolios one at a time. This is not a new problem. Recruiters once hand delivered physical portfolio binders to hiring managers across Manhattan. The binders are gone, but reviewing work one portfolio at a time has been slow to disappear.
A sparse match over human-authored metadata
Keyword search is a sparse, lexical match over metadata that humans wrote by hand. That design choice creates two problems.
First, it inherits the classic recall and precision problems of lexical information retrieval: synonymy (the same idea expressed in different words), vocabulary mismatch between the searcher and the creator, and no notion whatsoever of visual similarity. Two illustrations can look nearly identical and share zero tags.
Second, it introduces a labeling bottleneck. Most of the signal that matters in creative work—the images in a portfolio, the reels, the layout sensibility, the rendering style—is either not tagged at all, or it is tagged with a handful of broad labels that flatten what makes the work distinctive.
Consider a portfolio piece from a Graphic Designer: a character sculpt that reimagines an illustrated cartoon character as a photorealistic human.
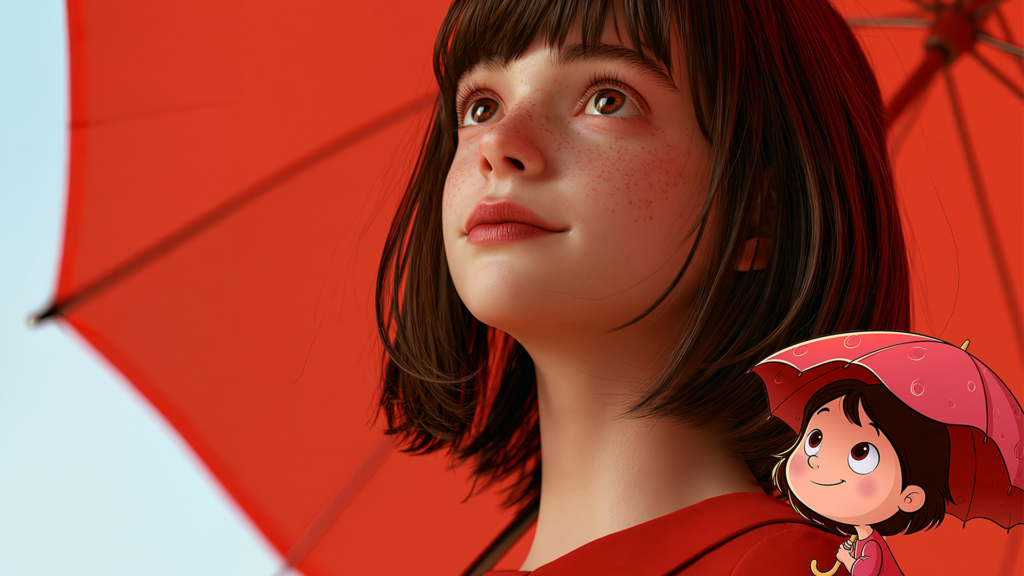
The tags attached to this piece are:
#Digital 3D #Realism #Character #Design #Character Modeling
Now compare that with a description built from the image and the context in the artist's portfolio:
A hyperrealistic 3D character sculpt of a cartoon girl holding red umbrella. This photorealistic portrait is rendered in an uncanny-valley style, featuring lifelike skin texturing and fine details, reimagining the iconic cartoon character in a realistic form.
The tags are not incorrect. They are just a tiny, lossy projection of what the work demonstrates. Skin shading, close-up portraiture, stylization-to-realism translation, studio lighting, and fine surface detail are skills a client might hire for, and none of them are searchable against the tags provided.
Quantifiable failure modes
That gap turns into concrete, measurable failures.
Recall loss
Qualified people never surface because their tags don't contain the query's exact words. A search for “Character Modeling” or “3D Character Model” would find the piece above. A search for “3D portrait with close-up studio lighting” or “3D character model with hyper-realistic texture,” which describes the work more precisely, would miss it entirely.
Precision loss
Profiles stuffed with keywords rank above better-matched but under-labeled ones. The ranking rewards whoever tagged most aggressively, not whoever did the most relevant work.
Unimodal, one-directional queries
Lexical search is text against text. If a Recruiter or client has a reference image that warrants a “we want something that looks like this” search, tags offer no way in. The most natural query in creative hiring is one the system cannot accept.
Design goals and constraints
Before choosing an architecture, we set out what Milton had to do and what it deliberately would not do.
- Recruiters use Milton.
- A written brief and a reference image should be equally valid starting points.
- Recruiters judge a search by its first screen. A relevant piece should appear near the top without scrolling.
- Portfolio images are not used to train models or to generate images. They are used only to match talent to roles.
The technical shift: joint embedding spaces for retrieval
One space for images, video, and text
Multimodal embedding models project images, video frames, and text into a shared vector space. Once everything lives in the same space, Milton can compare a text query and a portfolio image directly using cosine similarity instead of string matching.
The core idea is to represent all information about a piece of work in the same mathematical space so that similar items cluster together and dissimilar items sit far apart. SOTA models such as CLIP and ALIGN, popularized this approach by learning this alignment from large collections of image-caption pairs. Later work such as SigLIP and SigLIP 2 demonstrated the same at a larger scale. Research like VLM2Vec and MM-Embed shows how general vision-language models can be fine-tuned into universal multimodal retrievers.
The query defines similarity. A text query pulls results that match its meaning; an image query pulls results that look and feel like the reference; a combined query—an image plus “but in a flatter, more graphic style” can steer between the two.
At a system level, the pipeline has two paths that meet at a vector index.
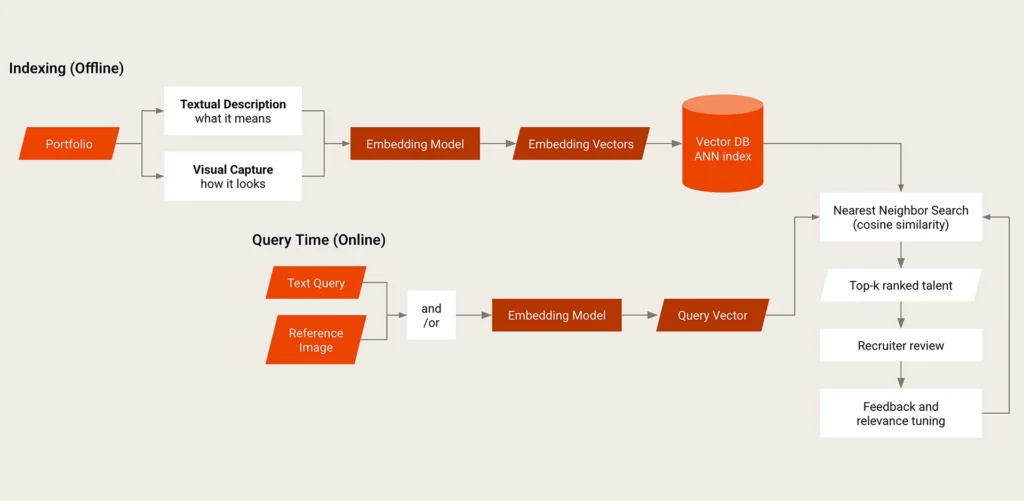
Figure 1 – Multimodal retrieval pipeline: portfolio content and query are encoded into the same vector space, matched through an approximate nearest-neighbor index and refined by Recruiter feedback.
How Milton puts this into practice
Milton follows the same two-path design shown in Figure 1.
For the offline processing that occurs once per image, Milton crawls and cleans each portfolio. Every image then gets a short written description of what it shows and what the Talent did. Milton embeds and stores both a visual capture of the image (how it looks) and its textual description (what it means) in an approximate nearest-neighbor (ANN) index.
For the online processing that occurs per query, a Recruiter enters a text brief and/or reference image, encoded by the same model and matched against the index. Results appear as a row of work samples per Talent, and Recruiters narrow them with practical filters: location, pay, and availability. When a Recruiter finds a fit, one click on the Make Candidate button moves the Talent into Aquent's submission workflow with Milton recorded as the source.
This architecture unlocks three capabilities that no amount of tag engineering can replicate.
- Similarity search – Example: “Find portfolios like this reference image.” Here, a single image becomes a complete query.
- Cross-modal search – Text-to-image and image-to-image queries run against the same index, so a written brief and a mood board can both drive retrieval.
- Semantic ranking – Results are ranked by learned semantic distance rather than term frequency, i.e., rather than counting how many tags happen to share words with the query.
However, embedding-based retrieval is not free, and the tradeoffs are real
Embedding quality and domain fit are important factors to be consider. General-purpose models are trained mostly on web imagery and captions. For creative staffing, the question is whether every style and artifact type (illustration, 3D, UI, typography, motion) can be represented meaningfully in one embedding space and whether that space can accommodate new creative styles as they emerge. Research also shows that embedding models have their own biases, for example, favoring content at certain positions in the input. This reminds us that dense vectors are powerful but not neutral.
The debate between latency and index size is another important tradeoff. Questions like “how many portfolio images you can host before search quality degrades” and “whether retrieval slows as the corpus grows” come down to a product constraint: how long will a recruiter look at a loading screen before the right Talent appears? ANN index parameters, embedding dimensionality, and techniques like variable-length embeddings all trade a little accuracy for a lot of speed and storage.
Lastly, evaluation is harder with embedding-based searches. The most fundamental question is how to define “relevant” for vector search over creative work. Is it human judgment, click-through rate, hiring outcomes, or some combination?
Milton takes an iterative approach. We started with a benchmark set, curated with experts weighing in on the best results for a set of standardized queries. On that benchmark of standardized queries, Milton's multimodal retrieval returns the right portfolio piece:
- In the top 5 results for 74% of queries (recall@5).
- In the top 10 results for 95% of queries (recall@10).
- In the top 20 results for 100% of queries (recall@20). Across all benchmark queries, the right match always appeared within the first 20 results.
In practice, this means a Recruiter will usually find the right piece on the first screen of results and, on this benchmark, never has to look past the top 20.
Now that the product is live, we also observe how users interact with results and what happens downstream. That signal is fed back into the underlying retrieval mechanism, so the system progressively corrects itself toward what a Recruiter would actually want to see.
Why this is the right investment for creative hiring
The artifact is multimodal by nature
Creative hiring is a domain where the work being evaluated is inherently multimodal. This makes it an unusually strong fit for joint embedding retrieval. Search today spans text and images, and the same architecture extends naturally to video and other modalities where demand is growing quickly. Adding a new modality means adding an encoder path into the same shared space rather than inventing a new tagging scheme.
Better system-level accuracy translates directly into faster, better-matched shortlists at scale. Recruiters spend less time translating briefs into keywords and more time evaluating genuinely relevant work. In broad terms, that means more successful matches between the right creative professional and the right client.
A differentiator in the talent acquisition (TA) and staffing-tech stack
Most talent platforms are still bound to lexical search. Shipping multimodal retrieval is both a technical advantage and a go-to-market one. It lets Recruiters and clients search the way creative people actually think.
It also changes how portfolio content moves through the system. Since retrieval operates on vector representations inside a controlled index, search can surface relevant work without widely redistributing raw portfolio assets, and access controls can be enforced at the index level. Embeddings are not a privacy guarantee on their own, but paired with careful data handling they give portfolio content an added guardrail.
What's next
Lexical search is fundamentally mismatched to multimodal creative work. Embedding-based retrieval is the architecture that lets creative search scale responsibly. It is not an add-on feature bolted onto a keyword engine.
Keyword and tag-based search hit a hard ceiling because they cannot represent what makes creative work good. These searches lose qualified talent to vocabulary mismatch, reward keyword volume over relevance, and cannot accept the most natural query in creative hiring: a reference image. Joint embedding spaces remove that ceiling by placing images, text, and queries in one space and ranking by meaning. They come with real engineering tradeoffs in domain fit, latency, and evaluation, which is why continuous, expert-grounded measurement matters as much as the model. Embedding models carry a higher up-front cost than a keyword index. But embedding-based search delivers better outcomes when hiring creative professionals, and over time those benefits outweigh the cost.
That foundation is what lets Milton keep growing. Next, we're working on reaching more of the work that matters. Many working creatives keep their best client work behind a password, so supporting password-protected sites is on the roadmap, and we're extending ingestion beyond personal sites to Behance and similar platforms. We're also making search proactive. Every new candidate who joins Aquent's network will be checked against clients' saved searches, so matching work shows up as soon as it's indexed rather than the next time someone runs a search. From there, we plan to extend the same shared embedding space to video and motion work, so those formats can be searched by meaning, just like images and text. Longer term, we're exploring whether clients could use Milton to search their own image libraries.
If you are building or buying search for creative talent, start by measuring your keyword ceiling. Run a set of held-out queries, check metrics, and see how much qualified work your current system never shows. Then talk to us about how Milton uses multimodal retrieval for creative hiring.
About the author

Nikita Gurudath is a Senior AI Engineer on Aquent's Technology & Innovation team, where she leads AI research and development, including the search behind Milton, Aquent's AI-powered creative talent portfolio search tool. She has more than 10 years of experience across industries in image processing, computer vision and machine learning, and is an inventor on 44 patents.Nikita is passionate about using AI ethically and for social good. A keen learner, she values cross-functional and cross-cultural collaboration. Outside of work, she loves to hike, travel and dance. Nikita holds a Master of Science in Electrical Engineering from Ohio University.
Latest.
How to choose between temp staffing vs. freelance marketplaces
Leadership & Management, Retention Strategies, Talent Acquisition & Recruitment

The entry-level creative role isn’t dead. It’s been rebuilt.
Leadership & Management, Retention Strategies, Talent Acquisition & Recruitment
AI portfolio search for creative hiring, meet Milton.
Leadership & Management, Engineering & Technology, Innovation & Emerging Tech, Talent Acquisition & Recruitment